
And on API too.

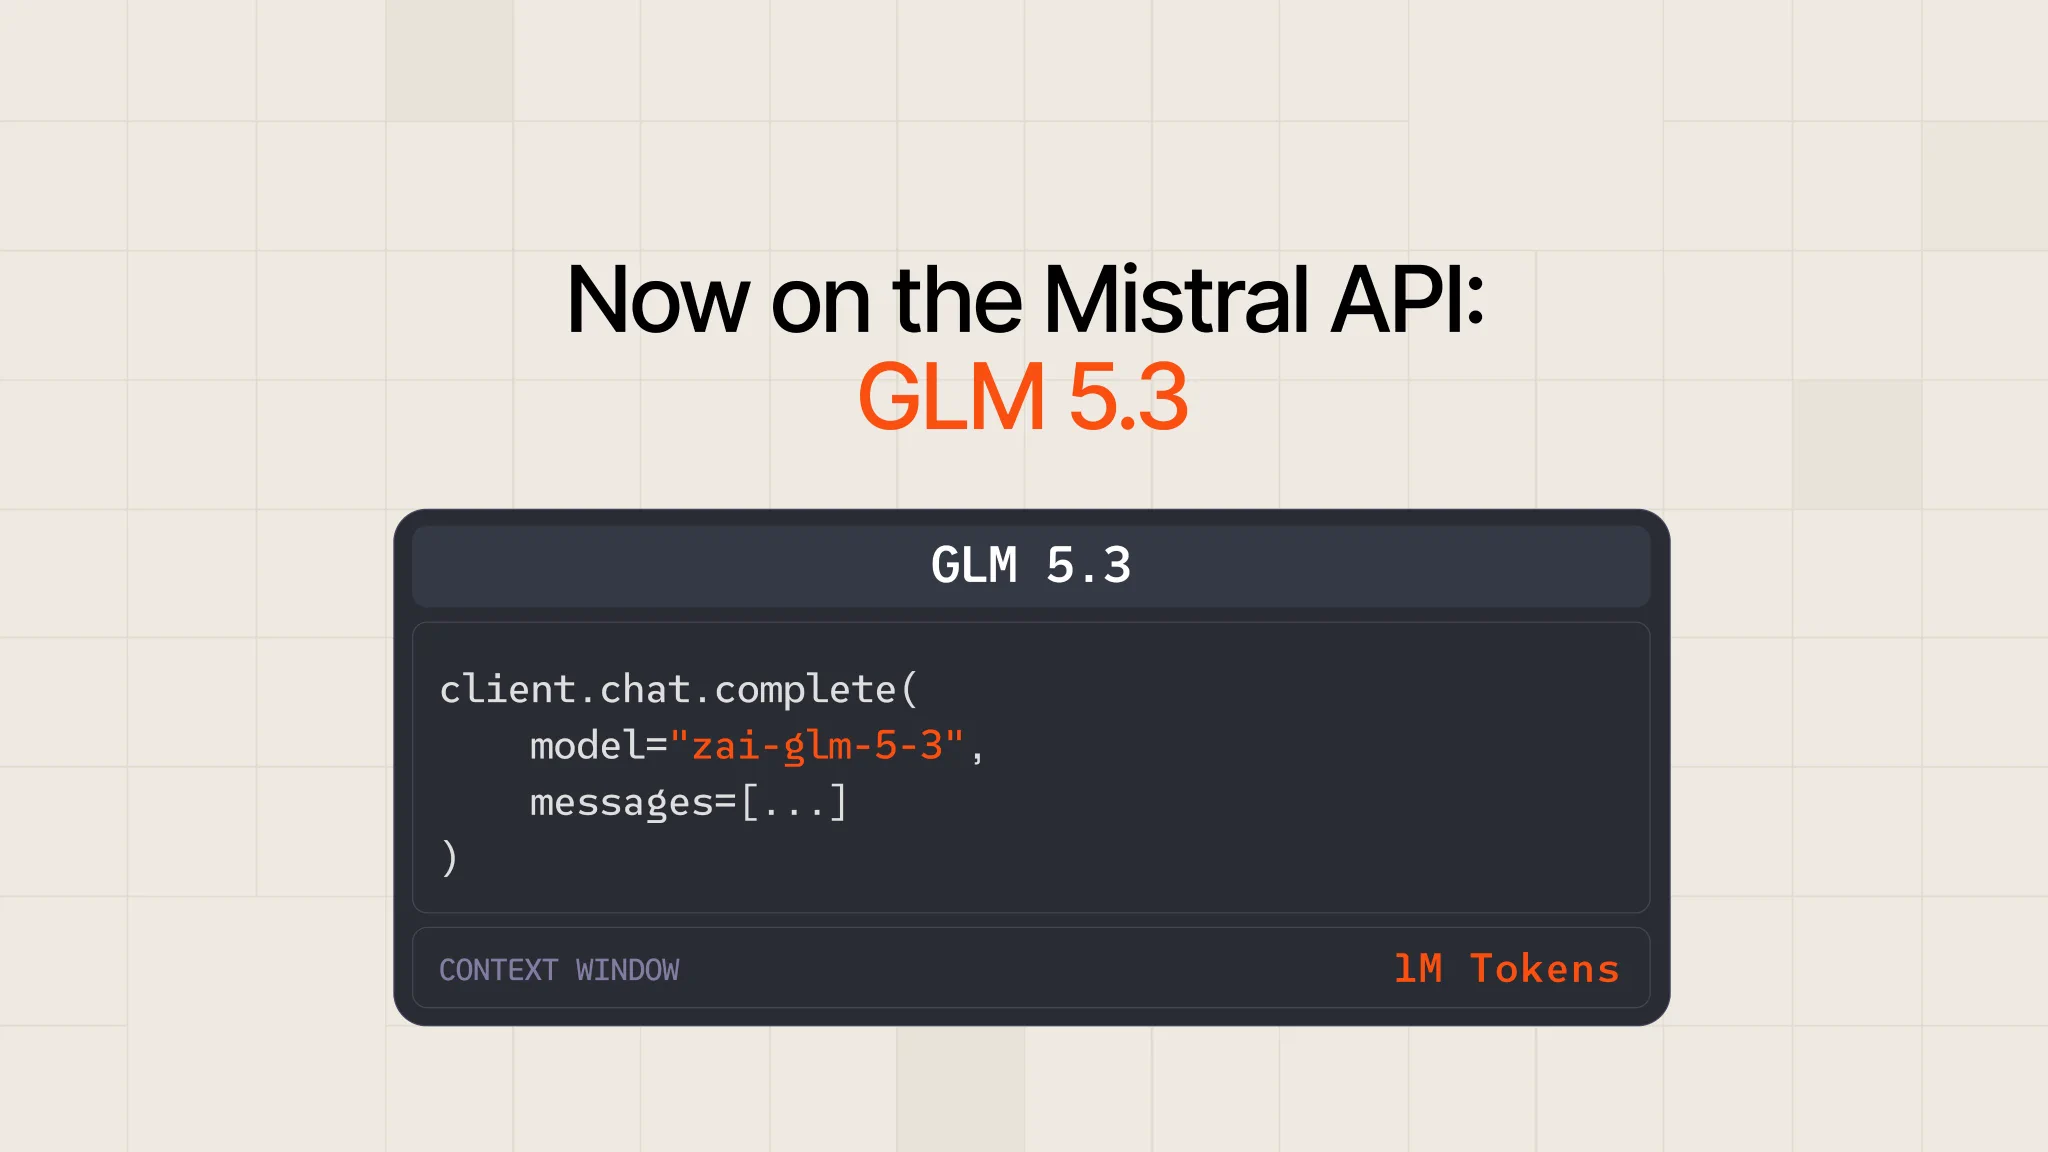
GLM 5.3 is now on the Mistral API.
- 1M-token context, a big step up from GLM 5.2 on long-horizon agentic coding.
- 100+ tok/s, served on Mistral's own infra.
- 99.5% uptime SLA (priority tier) and cached input up to 90% cheaper for repeated prompts.